

Surprising Factor About Index Selection
The Progress ABL Virtual Machine (AVM) doesn't always choose the same index you would as a developer. It follows a fixed set of selection rules and, in some cases, selects an index that seems less logical from a business perspective.
What Is a Database Index?
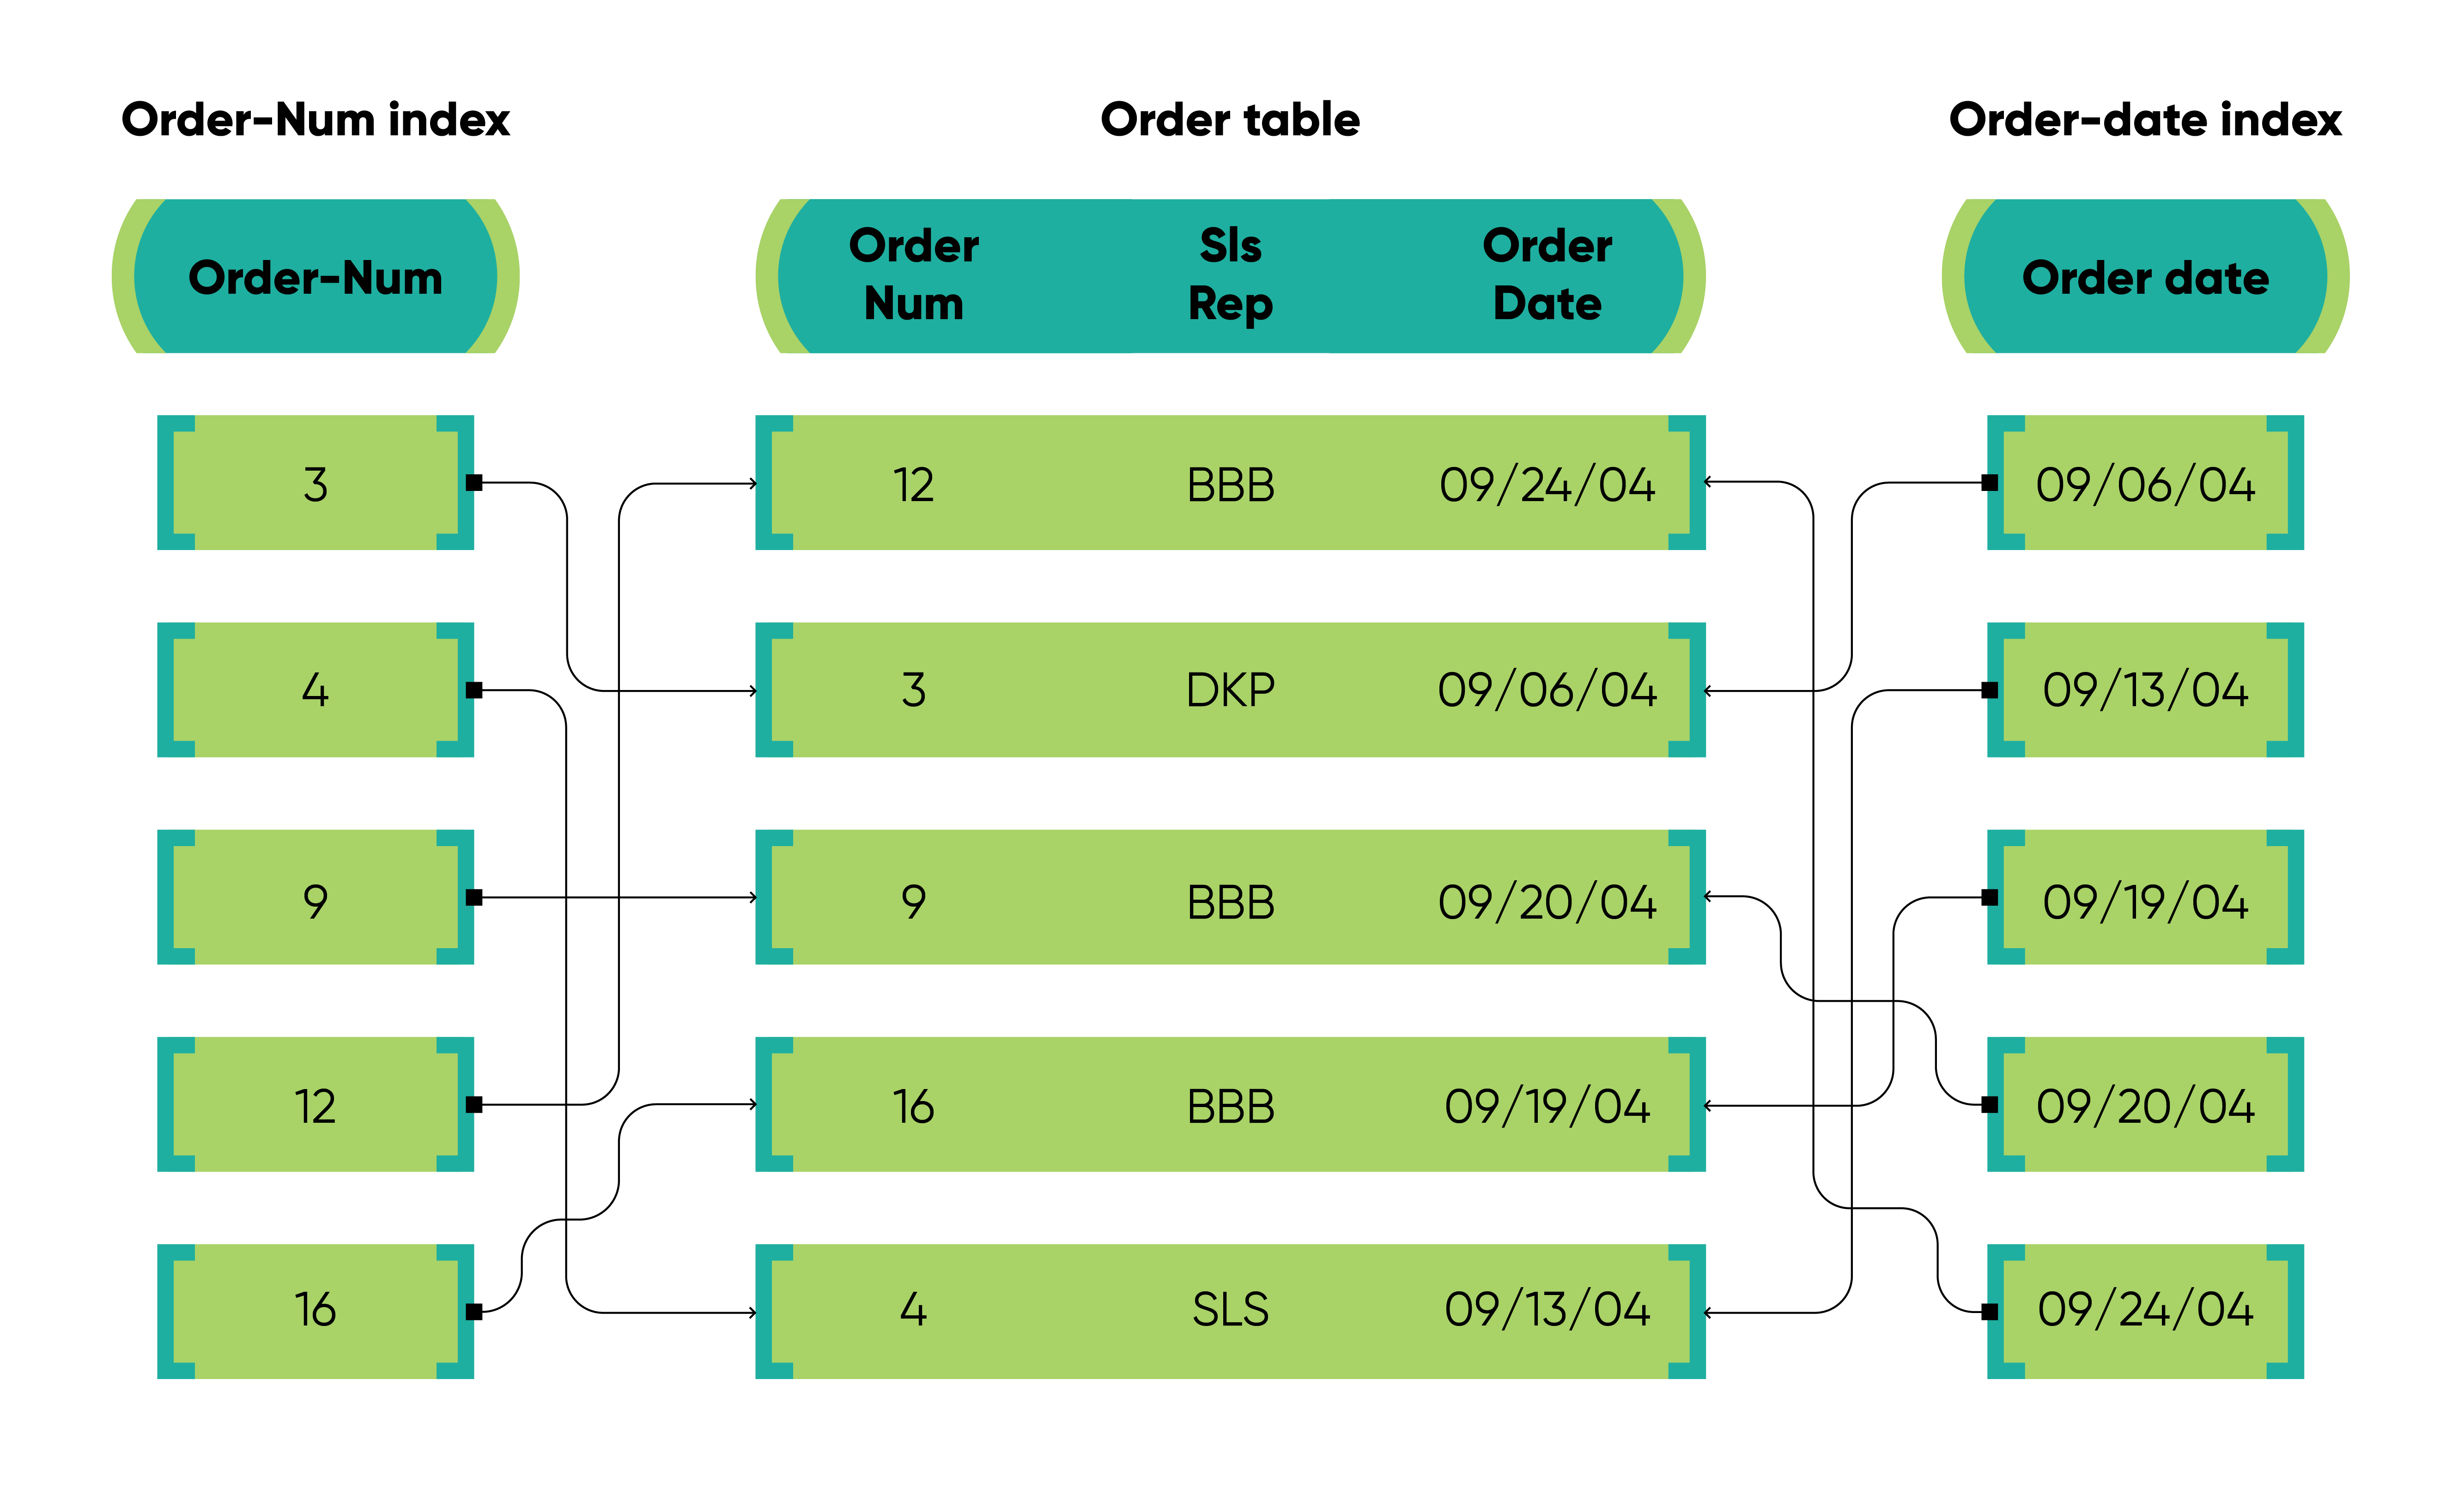
A database index works like a book index. Instead of reading every page, you check the index, find the topic, and go straight to the pages with the information.
Similarly, when you ask a database for specific data, the database engine uses an index to find it. An index contains two pieces of information: the index key and a row pointer that points to the corresponding row in the main table.
The figure below illustrates this using the Order table from the Sports2020 database.
Why Does Progress Index Selection Matter?
Progress AVM follows specific index selection and elimination rules based on the query, the available indexes, and the fields used in the WHERE or BY clause.
A typical flow looks like this:
- A user submits a request,
- The application generates a database query,
- Progress AVM evaluates the query,
- The AVM selects one or more indexes,
- The query returns the requested data.
If the database reads more records than necessary, the query takes longer to complete, and the user waits longer for the data.
That is why developers shouldn't focus only on whether a query returns the correct result. Understanding index selection helps you write queries that are both correct and efficient.
How Does Progress AVM Select an Index?
The AVM first eliminates unhelpful indexes, then selects the best remaining index based on matching rules. The main rules, in order of priority, are:
- Pre-select indexes whose leading components are used in the WHERE clause,
- If CONTAINS is used, use the word ‘index’,
- Prefer a unique index with all components involved in equality matches,
- Prefer the index with the most active equality matches,
- Prefer the index with the most active range matches (>, >=, <, and <=),
- Prefer the index with the most active sort matches,
- Use the primary index,
- Use the first index alphabetically by name (in temp-tables, the first index defined).
One important detail is the 'fuller field match' rule. An index with a 1/1 component match is considered fuller than an index with a 1/2 component match.
Why can a different index be chosen?
Suppose the OrderLine table has these indexes:
Now look at this query:
for each Order where Order.Ordernum < 100:
    for each OrderLine where (OrderLine.Ordernum = Order.Ordernum)
                       and OrderLine.ItemNum = 3:

    end.
end.
Without knowing the selection rules, a developer might expect the AVM to use both indexes, or assume that the 'obviously logical' orderline index would win because the query filters by OrderNum. However, the AVM selects only one index, and it picks itemnum, which scans far more records.
Why? Because the itemnum index has a full 1/1 match, while orderline has only a 1/2 match.
What Are the Available Tools?
You shouldn’t guess which index is used, verify it with tools instead. XREF, LOG-MANAGER, and PROMON each help you investigate query behaviour from a different angle:
Each tool has a different purpose:
Testing the example with XREF and PROMON
For the previous example, XREF confirmed which index was used:
1 COMPILE custom.p

1 CPINTERNAL ISO8859-1

1 CPSTREAM ISO8859-1

17 BLOCK-LEVEL ON ERROR UNDO, THROW

18 STRING "iCounter" 8 NONE UNTRANSLATABLE

21 STRING "Order" 5 NONE UNTRANSLATABLE

21 ACCESS sports2000.Order Ordernum

21 SEARCH sports2000.Order OrderNum

22 STRING "OrderLine" 9 NONE UNTRANSLATABLE

22 ACCESS sports2000.OrderLine Ordernum

22 ACCESS sports2000.Order Ordernum

22 ACCESS sports2000.OrderLine Itemnum

22 SEARCH sports2000.OrderLine itemnum
PROMON then showed how many records were read:
The query produced 26,294 database reads.
To cut those reads, I added AND OrderLine.LineNum > 0 to the WHERE clause:
for each Order where Order.Ordernum < 100:
    for each OrderLine where (OrderLine.Ordernum = Order.Ordernum and OrderLine.LineNum > 0)
                       and OrderLine.ItemNum = 3:

    end.
end.
This reduced the record reads to 864, and the selected index changed to orderline. PROMON and XREF both confirmed the result:
1 COMPILE custom.p

1 CPINTERNAL ISO8859-1

1 CPSTREAM ISO8859-1

17 BLOCK-LEVEL ON ERROR UNDO, THROW

18 STRING "iCounter" 8 NONE UNTRANSLATABLE

21 STRING "Order" 5 NONE UNTRANSLATABLE

21 ACCESS sports2000.Order Ordernum

21 SEARCH sports2000.Order OrderNum

22 STRING "OrderLine" 9 NONE UNTRANSLATABLE

22 ACCESS sports2000.OrderLine Ordernum

22 ACCESS sports2000.Order Ordernum

22 ACCESS sports2000.OrderLine Itemnum

22 ACCESS sports2000.OrderLine Linenum

22 SEARCH sports2000.OrderLine orderline
However, it also introduced a new risk.
Why is a 'smart' WHERE clause risky?
In the Sports2020 database, OrderLine records have LineNum values starting at 1, so the 'smart' query caused no problems.
However, if the database has no constraint preventing LineNum from being 0 or negative, the query may silently return incorrect results.
This creates three problems:
- Data correctness risk. The query depends on an assumption that the database may not enforce.
- Maintenance complexity. Future developers may not understand why AND LineNum > 0 was added.
- Hidden performance trade-offs. The query may reduce record reads, but in some cases, it could still increase index block reads.
Should Developers Use USE-INDEX?
Developers should not use USE-INDEX as a default solution. It can help, but only if you understand why the AVM chose a different index and why the forced index is better.
USE-INDEX also has disadvantages:
- It bypasses the AVM's normal index selection logic,
- It can become outdated if the database schema changes,
- It can hide deeper design issues,
- It can make the code less flexible.
Still, USE-INDEX is the best option in some cases. In my example, USE-INDEX orderline is a better fit than the 'smart' WHERE clause, because it gets the same efficient index without relying on an assumption about LineNum values.
The main rule is simple: use USE-INDEX only when you have measured the query, checked the alternatives, and understood the impact.
What Is the Best Way to Optimise ABL Queries?
The best way to optimise ABL queries is to combine index-selection knowledge with measurement. Understand the rules, inspect the selected indexes, measure database reads, and validate every change.
In practice, that means following the same loop used in this article: write the query, confirm the index with XREF, measure reads with PROMON, adjust, and re-test.
Key Takeaways for ABL Query Performance
Good query performance isn’t just about writing a correct WHERE clause. It’s also about understanding how Progress AVM interprets it. In my testing, a single index-selection difference turned 26,294 reads into 864. For an application that runs that query hundreds of times a day, the gap between those two numbers is the difference between a screen that loads in a second and one that makes a user think the system is broken.
The main lessons from this test are:
- Progress AVM selects indexes by fixed rules, not by business logic. A fuller match (1/1) beats a partial match (1/2), even if it reads far more records.
- Never guess which index is used. Confirm it with XREF and measure reads with PROMON before and after every change.
- A ‘smart’ WHERE condition can change the selected index, but it can also return incorrect results if the underlying data assumption isn’t enforced.
- USE-INDEX is a deliberate tool for measured cases, not a default fix.
Progress index selection is predictable once you know the rules, even when it isn’t intuitive. Make XREF and PROMON checks part of your regular development and code-review routine, prefer fixes that keep queries correct and readable, and you’ll catch slow queries long before your users do.
If your organisation wants to improve the performance of its ABL applications or extend its Progress OpenEdge systems, visit the Progress OpenEdge product page to learn more about the platform and its wider ecosystem.